Creating TDSQL for MySQL Data Subscription
Unduh
Mode fokus
Ukuran font
This scenario describes how to use DTS to create a data subscription task for TencentDB for TDSQL MySQL.
Prerequisites
Prepare the source TencentDB for subscription and ensure that its version meets the requirements. For more information, see databases supported by data subscription.
binlog has been enabled on the source instance.
A subscription account has been created on the source instance. The account requires the following permissions: REPLICATION CLIENT, REPLICATION SLAVE, PROCESS, and SELECT on all objects.
The specific grant statements are as follows:
create user 'migration account' IDENTIFIED BY 'account password';grant SELECT, REPLICATION CLIENT,REPLICATION SLAVE,PROCESS on *.* to 'migration account'@'%';flush privileges;
Restrictions
1. Subscribed messages are stored in the built-in Kafka (single Topic) of DTS. Currently, the default retention period is 1 day, and the maximum storage per Topic is 500 GB. When the data retention period exceeds 1 day or the data volume exceeds 500 GB, the built-in Kafka starts to purge the earliest written data. Therefore, consume the data promptly to avoid data being purged before it is fully consumed.
2. The region for data consumption must be the same as the region of the subscription task.
3. Geometry-related data types are currently not supported.
4. When the data subscription source is TDSQL for MySQL, you cannot grant permissions by directly executing grant statements. Instead, add the permissions for the subscription account in the TDSQL console by clicking the instance ID and going to the account management page.
5. The permissions required by the subscription account are those shown in the grant statements above. To grant permissions on
__tencentdb__ to the subscription account, select object-level privileges in the permission modification dialog box in the console and select all permissions.6. When the data subscription source is TDSQL for MySQL, subscribing to secondary partitioned tables is not supported.
6.1 If a secondary partitioned table is created in the source database before the subscription task starts, the check task will fail.
6.2 If a secondary partitioned table is created in the source database while a subscription task is running, the data subscribed from the secondary partitioned table is subtable data. This is because if the subscription object is an entire database or instance, secondary partitioned tables created in the source database after the subscription task starts are also subscribed, resulting in the subscription of secondary partitioned tables. Since secondary partitioned tables are implemented through subtables at the underlying level, it is not recommended to create secondary partitioned tables during a subscription task. Otherwise, subscription data differences will occur as shown in the following example.
Example: If the source database table "test_a" is a secondary partitioned table, the table name in the DML subscribed by DTS will be "test_a_tdsql_subp0/test_a_tdsql_subp1".
7. During a subscription task, operations such as modifying subscription objects cause a task restart, which may result in duplicate data when users consume data from the Kafka client.
7.1 DTS transfers data by the smallest data unit. In incremental data transfer, each marked checkpoint is a data unit. If a data unit has just been transferred when a restart occurs, no data duplication will be caused. If a data unit is still being transferred when a restart occurs, the data unit needs to be pulled again after the restart to ensure data integrity, which will cause data duplication.
7.2 If you are concerned about duplicate data, configure deduplication logic when consuming data.
8. A source TDSQL for MySQL instance can contain up to 5,000 tables. Exceeding this limit will cause Data Transfer Service (DTS) tasks to report errors. Additionally, an excessive number of tables can increase access latency on the source, resulting in performance jitter and degradation.
Note
For subscription tasks where the data subscription source is TDSQL for MySQL, DDL operations on all shards are subscribed and delivered to Kafka. Therefore, duplicate DDL statements occur for a DDL operation on a sharded table. For example, if instance A has 3 shards and subscribes to a sharded table named tableA, the DDL statement for tableA is subscribed 3 times.
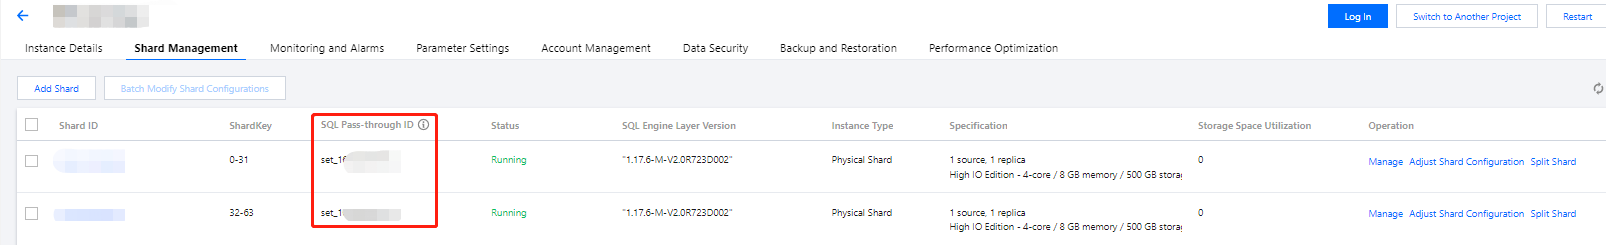
The header of each message in Kafka carries shard information in key/value form, where the key is ShardId and the value is the SQL passthrough ID. You can identify the shard from which a message originates based on the SQL passthrough ID. You can view the SQL passthrough ID in the TDSQL console under > Instance List > Shard Management.
Supported SQL Operations for Subscription
Operation Type | Supported SQL Operations |
DML | INSERT,UPDATE,DELETE |
DDL | CREATE DATABASE,DROP DATABASE,CREATE TABLE,ALTER TABLE,DROP TABLE,RENAME TABLE |
Operation Steps
1. Log in to the DTS console, select Data Subscription in the left sidebar, and click Create Subscription.
2. On the Create Subscription page, select the corresponding configuration, and click Buy Now.
Parameter | Description |
Billing Mode | The yearly/monthly subscription and pay-as-you-go modes are supported. |
Database | Select based on the specific database type. |
Region | If the source database is a TencentDB instance, the region here must be consistent with the region of the source database instance. If the source database is not a TencentDB instance, the region here must be consistent with the region where data is consumed. If there is no special requirement for the data consumption region, select the region closest to the source database. |
Edition | Select 2.0. |
Specification | Select a specification based on your business requirements. |
Tag | Set tag keys and values for subscription tasks to efficiently manage multiple tasks through tags. |
Subscribed Instance Name | Select Name After Creation: The default task name will be the same as the task ID. You can rename the task after the subscription task is created. Set it to Name Now. Enter the task name in the input box below. |
Terms of Service |
3. After the purchase is successful, return to the subscription list, click Configure Subscription in the Operation column to configure the newly purchased subscription. You can use it only after the configuration is completed.
4. On the Configure data subscription page, select the data subscription task. After completing the configuration, click Test Connectivity. After the test is successful and the network is configured, click Save and Go Next.
Data Subscription Task Settings
Configuration Item | Description |
Instance Type | Database type selected during creation. It cannot be modified. |
Access Type | Currently, only scenarios where the source database is a TencentDB instance are supported. Select "Cloud Database". |
Instance Name | Cloud database instance: instance ID of the source database. Read-only/disaster recovery instances can be selected, but selecting the primary instance is recommended, as the subscription service imposes minimal load on the source database. |
Account/Password | Account and password of the source database. |
Network Settings
Configuration Item | Description |
Network | Specify in advance the VPC environment for accessing the Kafka of the subscription task (including the VPC and subnet). You can then consume the data subscription service through this VPC. Note: Access within the same VPC: All CVMs in the same VPC can access subscription data normally without additional configuration. Cross-VPC access: If the consumer CVM is in another VPC, you need to configure CCN to enable cross-VPC access. |
5. On the Subscription Type and Object Selection page, select the subscription type, and click Save and Go Next.
Configuration Item | Description |
Subscription Type | Data update: Subscribes to data updates for all objects in the source database, including INSERT, UPDATE, and DELETE operations. Structure update: Subscribes to the creation, modification, and deletion of structures for all objects in the source database. All instances: Subscribes to data updates and structure updates for all objects in the source database. |
Kafka Version | Displays the version of the built-in Kafka in DTS. It cannot be modified. |
Number of Topic Partitions | Set the number of partitions for topics in the built-in Kafka for data delivery. Increasing the number of partitions can improve the speed of data write operations and consumption. A single partition can guarantee message order, while multiple partitions cannot. If you have strict requirements on the order of consumed messages, select 1 as the number of partitions. |
Topic Partition Policy | Partition by table name: Write data with the same table name into the same partition. Partition by table name + primary key: Data with the same primary key is written to the same partition. This method is suitable for tables with hot data, as it distributes hot table data across different partitions to improve concurrent consumption efficiency. |
6. On the pre-check page, the pre-check task is expected to run for 2 to 3 minutes. After the pre-check is passed, click Start to complete the data subscription task configuration.
Note:
7. After you click Start, the subscription task will be initialized. This process is expected to take 3 - 4 minutes. After successful initialization, the task enters the Running state.
8. Create Consumer Group: Data Subscription for Kafka allows users to create multiple consumer groups (up to 10 consumer groups per subscription task) for multi-point consumption. Data consumption in Data Subscription for Kafka relies on Kafka consumer groups, so you need to create a consumer group before consuming data.
9. After the subscription instance enters the Running state, you can start consuming data. Kafka consumption requires password authentication. For specific examples, see Data Consumption Demo, where we provide Demo code in multiple languages and explain the main consumption process and key data structures.
Bantuan dan Dukungan
Apakah halaman ini membantu?
Anda juga dapat Menghubungi Penjualan atau Mengirimkan Tiket untuk meminta bantuan.
masukan