Guide to Consuming MySQL Series Subscription Data
Baixar
Modo Foco
Tamanho da Fonte
Overview
This operation applies to data subscription for MySQL/TDSQL-C MySQL/MariaDB/Percona/TDSQL MySQL. In the Kafka edition of data subscription (the current Kafka Server version is V2.6.0), you can consume subscription data through a Kafka client of version 0.11 or later. This document provides client consumption Demo examples in Java, Go, and Python to help you quickly test the data consumption process and understand how to parse data formats.
Note
1. The Demo does not include a demonstration of how to consume data. It only prints the data, so you need to write your own data processing logic based on it. You can also use Kafka clients in other languages to consume and parse data.
2. Currently, consuming data by connecting to the Kafka of data subscription over the public network is not supported. Access is supported only through the Tencent Cloud private network, and the region of the subscribed database instance must be the same as the region where data is consumed.
3. When Avro or JSON is selected as the data format, DTS subscription has the following limitations in handling large messages.
For tasks created before March 25, 2024, DTS subscription has a certain limit on processing a single message. When a single row of data in the source database exceeds 5 MB, the subscription task may report an error.
For tasks created on or after March 25, 2024, no error will be reported by the subscription task when a single row of data in the source database exceeds 5 MB. You can use the latest consumption Demo to obtain the consumption data of large messages.
4. When you subscribe to specified database/table objects (not all objects in the source instance) and use a single Kafka partition, DTS parses the incremental data and writes only the data of the subscribed objects to the Kafka Topic. Data of non-subscribed objects is converted into empty transactions and written to the Kafka Topic, so empty transactions appear during data consumption. The Begin/Commit messages of empty transactions retain the GTID information of the transactions, ensuring the continuity and integrity of GTIDs. In addition, in the consumption Demo for MySQL/TDSQL-C MySQL, multiple empty transactions are compressed to reduce the number of messages.
5. To ensure data reentrancy, DTS subscription introduces a Checkpoint mechanism. When messages are written to the Kafka Topic, a Checkpoint is generally inserted every 10 seconds to mark the data synchronization checkpoint. After a task is interrupted and restarted, the breakpoint position is identified to implement resumable transfer. In addition, when the consumer encounters a Checkpoint message, it commits the Kafka consumption offset once to update the consumption offset in a timely manner.
6. When JSON is selected as the data format, if you have used or are familiar with the open-source subscription tool Canal, you can convert the consumed JSON data into a data format compatible with Canal for subsequent processing. Our Demo already provides support for this. You can enable it by adding the parameter trans2canal to the startup parameters of the Demo. Currently, this feature is supported only in Java.
7. When ProtoBuf or JSON is selected as the data format, DTS converts numeric types from the source MySQL to string types when writing to Kafka. For FLOAT and DOUBLE types, if the absolute value is less than 1e-4 or greater than or equal to 1e+6 when the value is converted to a string, the result is represented in scientific notation. Scientific notation represents floating-point numbers as a mantissa multiplied by a power of 10, which more clearly indicates the magnitude and precise value while saving storage space. If you need to convert the data back to numeric types on the consumer side, pay attention to special handling of floating-point strings represented in scientific notation.
8. When JSON is selected as the data format for a subscription task, if the source MySQL parameter
binlog_row_image is set to minimal, the values of unchanged fields in the consumed UPDATE statements will be missing. This is because the implementation of minimal only records affected columns to the binlog and does not record unaffected columns. To distinguish these missing values from NULL, DTS uses ##DTS_NA_VALUE## to represent the values of unchanged fields.If you want the UPDATE statements in the consumption results to include the values of unchanged fields, set the source MySQL parameter
binlog_row_image to full and then recreate the subscription task.Since ProtoBuf and Avro are binary formats, they do not require special strings to distinguish missing field values from NULL values, so this issue does not apply to them.
9. During background inspection, DTS creates a consumer group to consume the user's Kafka offset information and checks whether consumption progresses normally.
Downloading Demos
When configuring a subscription task, you can choose from different subscription data formats: ProtoBuf, Avro, and JSON. ProtoBuf and Avro use binary formats, which offer higher consumption efficiency, while JSON uses a lightweight text format, which is simpler and easier to use. You need to download the Demo corresponding to the format selected in the subscription task.
The following Demo example already includes the corresponding Protobuf/Avro/JSON protocol files, so you do not need to download them separately. If you choose to download the Protobuf protocol file yourself, use Protobuf 3.X for code generation to ensure correct compatibility of the data structures.
For the logic explanation and key parameter descriptions in the Demo, see Demo Description.
Demo Language | ProtoBuf(MySQL/MariaDB/TDSQL-C MySQL/Percona) | ProtoBuf(TDSQL MySQL) | Avro(MySQL/TDSQL-C MySQL) | Avro (MySQL/TDSQL-C MySQL) Data Format Compatible with Alibaba Cloud Subscription Service | JSON(MySQL/TDSQL-C MySQL) |
Go | - | ||||
Java | |||||
Python | - |
Steps for Running the Java Demo
Compilation environment: Maven or Gradle package management tool, JDK8.
Runtime environment: Tencent CVM (must be in the same region as the subscription instance to access the private network address of the Kafka server), with JRE8 installed.
The operation steps are as follows:
1. Create a new data subscription task. For details, see Data Subscription (Kafka Edition).
2. Create one or multiple consumption groups. For details, see Adding Consumer Group.
3. Download the Java Demo and decompress it.
4. Go to the decompressed directory. For ease of use, the directory contains Maven model files, the pom.xml file, and Gradle-related configuration files. You can choose the appropriate one as needed.
Package the project with Maven: Running mvn clean package.
Package the project with Gradle: Running gradle fatJar (with all dependencies contained) or gradle jar.
5. Run the Demo.
After packaging with Maven, go to the target folder and run
java -jar sub_demo-1.0-SNAPSHOT-jar-with-dependencies.jar --brokers=xxx --topic=xxx --group=xxx --user=xxx --password=xxx --trans2sqlAfter packaging with Gradle, go to the build/libs folder and run
java -jar sub_demo-with-dependencies-1.0-SNAPSHOT.jar --brokers=xxx --topic=xxx --group=xxx --user=xxx --password=xxx --trans2sqlThe detailed description of each parameter is as follows:
Parameter | Description |
brokers | Private access address of the data subscription Kafka. You can view it on the Subscription Details page. |
topic | |
group | |
user/password | |
trans2sql | Indicates whether to convert to SQL statements. If this parameter is included, the data is converted to SQL statements; if not, no conversion is performed. |
trans2canal | Optional. Supported only for the JSON data format and limited to the Java language. When JSON is selected as the data format, JSON data can be converted into a data format compatible with the Canal tool. If this parameter is included, the data is converted to Canal format; if not, no conversion is performed. |
6. Observe consumption.
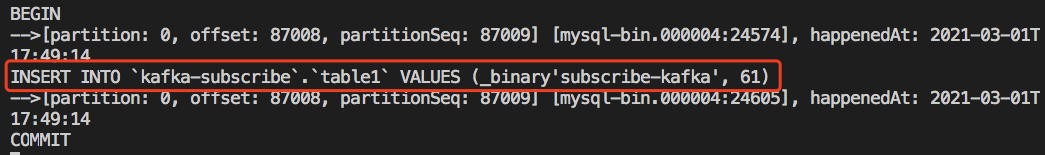
You can also use an IDE to compile and package the project. After packaging, the sub_demo-1.0-SNAPSHOT-jar-with-dependencies file in the target folder under the project root directory is a runnable jar package that contains all required dependencies.
Steps for Running the Golang Demo
Compilation environment: Golang 1.12 or later, with the Go Module environment configured.
Runtime environment: Tencent CVM (must be in the same region as the subscription instance to access the private network address of the Kafka server).
The operation steps are as follows:
1. Create a new data subscription task. For details, see Data Subscription (Kafka Edition).
2. Create one or multiple consumption groups. For details, see Adding Consumer Group.
3. Download the Golang Demo and decompress it.
4. Go to the decompressed directory and run
go build -o subscribe ./main to generate the executable file subscribe.5. Run the following code:
/subscribe --brokers=xxx --topic=xxx --group=xxx --user=xxx --password=xxx --trans2sql=true
brokers is the private network access address of the data subscription Kafka, and topic is the subscription topic of the data subscription task. You can view both on the Subscription Details page. group, user, and password are the name, account, and password of the consumption group, which can be viewed on the Consumption Management page. trans2sql indicates whether to convert the data into SQL statements.6. Observe consumption.
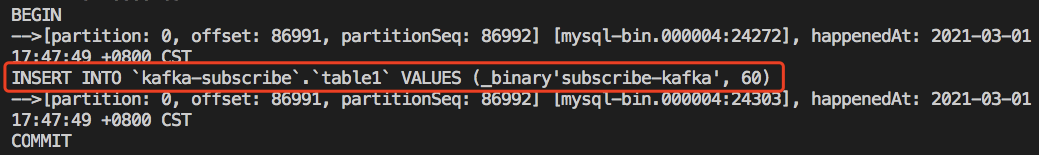
Steps for Running the Python3 Demo
Compilation and runtime environment: Tencent CVM (must be in the same region as the subscription instance to access the private network address of the Kafka server), with Python3 and pip3 installed (for dependency package installation).
Use pip3 to install dependency packages:
pip install flagpip install kafka-pythonpip install protobuf
The operation steps are as follows:
1. Create a new data subscription task. For details, see Data Subscription (Kafka Edition).
2. Create one or multiple consumption groups. For details, see Adding Consumer Group.
3. Download the Python 3 Demo and decompress it.
4. Run the following code:
python main.py --brokers=xxx --topic=xxx --group=xxx --user=xxx --password=xxx --trans2sql=1
brokers is the private network access address of the data subscription Kafka, and topic is the subscription topic of the data subscription task. You can view both on the Subscription Details page. group, user, and password are the name, account, and password of the consumption group, which can be viewed on the Consumption Management page. trans2sql indicates whether to convert the data into SQL statements.5. Observe consumption.
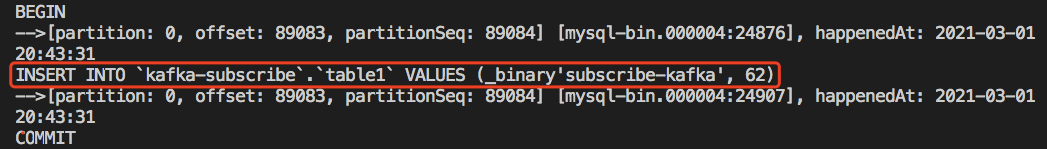
Ajuda e Suporte
Esta página foi útil?
Você também pode entrar em contato com a Equipe de vendas ou Enviar um tíquete em caso de ajuda.
comentários