
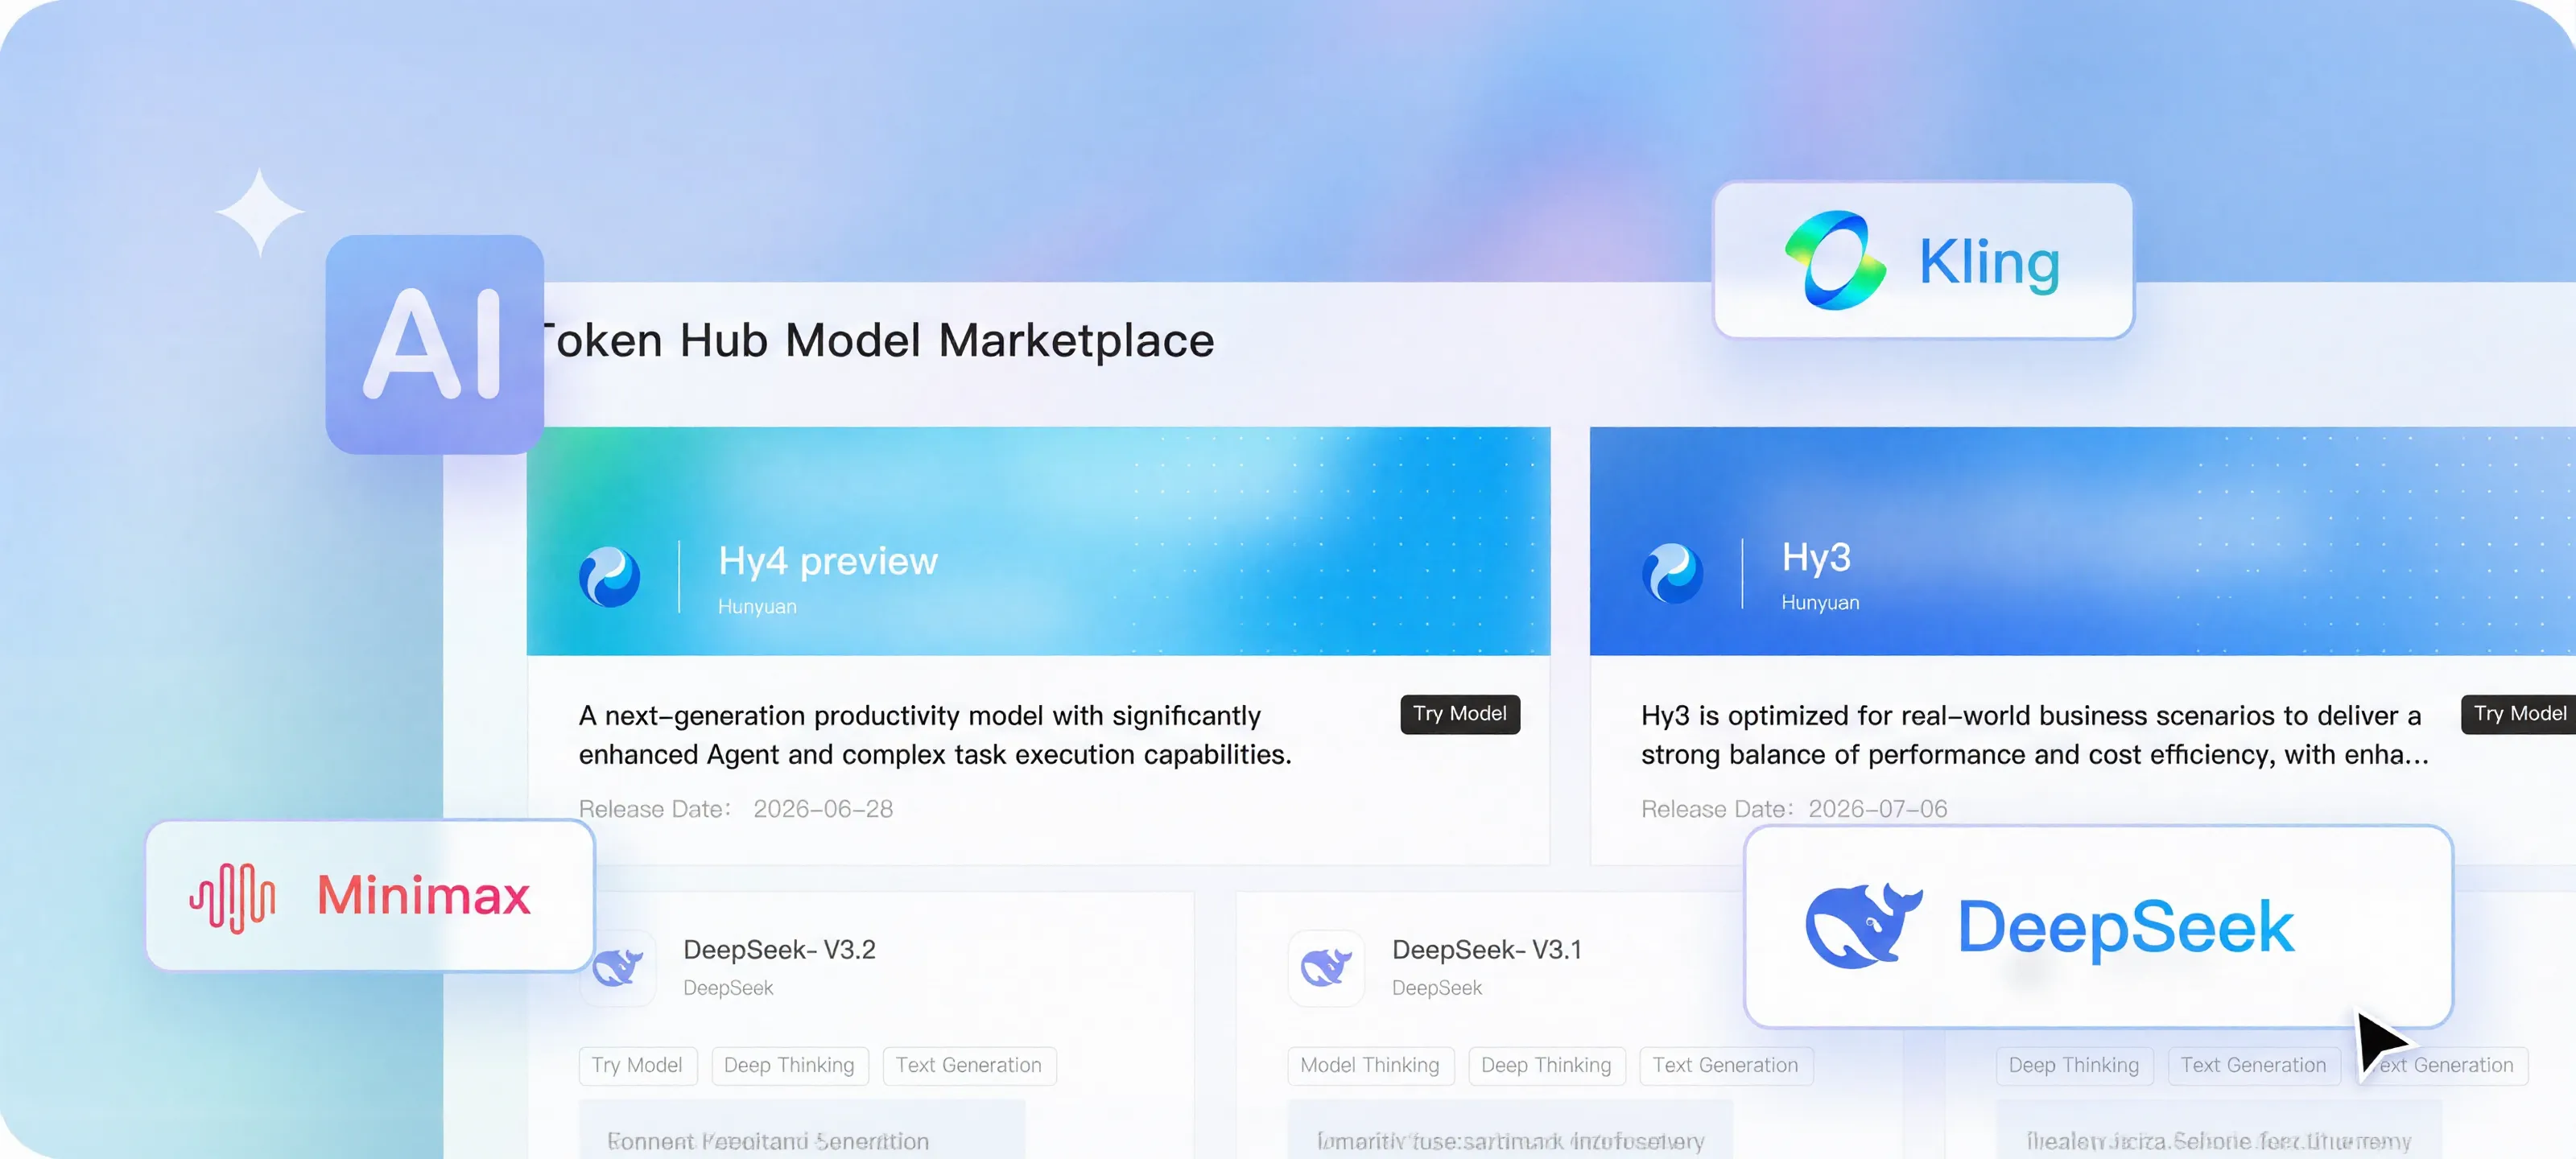
A next-generation productivity model with significantly enhanced Agent and complex task execution capabilities.
A next-generation productivity model with significantly enhanced Agent and complex task execution capabilities.

GLM-5.3-FlashX is a multimodal understanding model from Zhipu AI, featuring 1M context length and inference speeds of up to 200 tokens/s, delivering a faster and smoother model experience.
GLM-5.3-FlashX is a multimodal understanding model from Zhipu AI, featuring 1M context length and inference speeds of up to 200 tokens/s, delivering a faster and smoother model experience.

Zhipu's first natively multimodal model, delivering intelligence that surpasses GLM-5.2 through an ultra-low-cost architecture.
Zhipu's first natively multimodal model, delivering intelligence that surpasses GLM-5.2 through an ultra-low-cost architecture.

DeepSeek’s latest multimodal model has comprehensively outperformed V4 Pro across metrics including performance, cost, speed, and total latency.
DeepSeek’s latest multimodal model has comprehensively outperformed V4 Pro across metrics including performance, cost, speed, and total latency.

1.6 trillion-parameter MoE flagship with native 1M-token context, purpose-built for complex workflows.
1.6 trillion-parameter MoE flagship with native 1M-token context, purpose-built for complex workflows.

Native Multimodal Understanding and Generation: Supports diverse inputs and outputs—including text, images, audio, and video—to enable integrated content creation.
Native Multimodal Understanding and Generation: Supports diverse inputs and outputs—including text, images, audio, and video—to enable integrated content creation.
A next-generation productivity model with significantly enhanced Agent and complex task execution capabilities.
GLM-5.3-FlashX is a multimodal understanding model from Zhipu AI, featuring 1M context length and inference speeds of up to 200 tokens/s, delivering a faster and smoother model experience.
Zhipu's first natively multimodal model, delivering intelligence that surpasses GLM-5.2 through an ultra-low-cost architecture.
DeepSeek’s latest multimodal model has comprehensively outperformed V4 Pro across metrics including performance, cost, speed, and total latency.
1.6 trillion-parameter MoE flagship with native 1M-token context, purpose-built for complex workflows.
Native Multimodal Understanding and Generation: Supports diverse inputs and outputs—including text, images, audio, and video—to enable integrated content creation.


- Text Creation & Processing — Supports copywriting, rewriting & polishing, content summarization, multilingual translation, long-text analysis, and more.
- Dialogue & Q&A — Provides intelligent conversation, knowledge Q&A, logical reasoning, and solution recommendations.
- Code & Technical Generation — Supports code writing, SQL generation, script development, and technical documentation authoring. Title: Code Generation

- Powered by the Hy large-scale model, it delivers robust Chinese semantic understanding and precise control over imagery. It accurately generates highly consistent characters, scenes, and storyboard assets, meeting the demands for professional-grade, high-precision image creation.
- Integrating capabilities from cutting-edge global commercial models, it offers exceptional stylistic diversity and artistic expression. It enables the rapid exploration of diverse visual styles during asset production, generating images that are both creative and market-ready.

- It supports Hy as well as mainstream third-party video generation models such as MiniMax, Kling, and Vidu, delivering high-resolution, stylistically diverse, and controllable output, alongside capabilities like video enhancement and object removal.
- Tailored to the needs of sectors such as education, advertising and marketing, and short-form drama, it offers a wide range of applications—including document-to-video conversion, video stylization (re-rendering), text-to-short-drama generation, viral content replication, and viral video distribution. These features are launching soon; stay tuned.

- 3D Model Generation — Supports generating 3D models from various inputs, such as text, images, and sketches.
- World Models — Supports generating editable and interactive 3D scene files from text and images.


